Compaction and Summarization: Surviving the Window
Compaction keeps a long-running system within budget by preserving some information exactly, representing some more briefly, retrieving some later, and deliberately losing the rest.
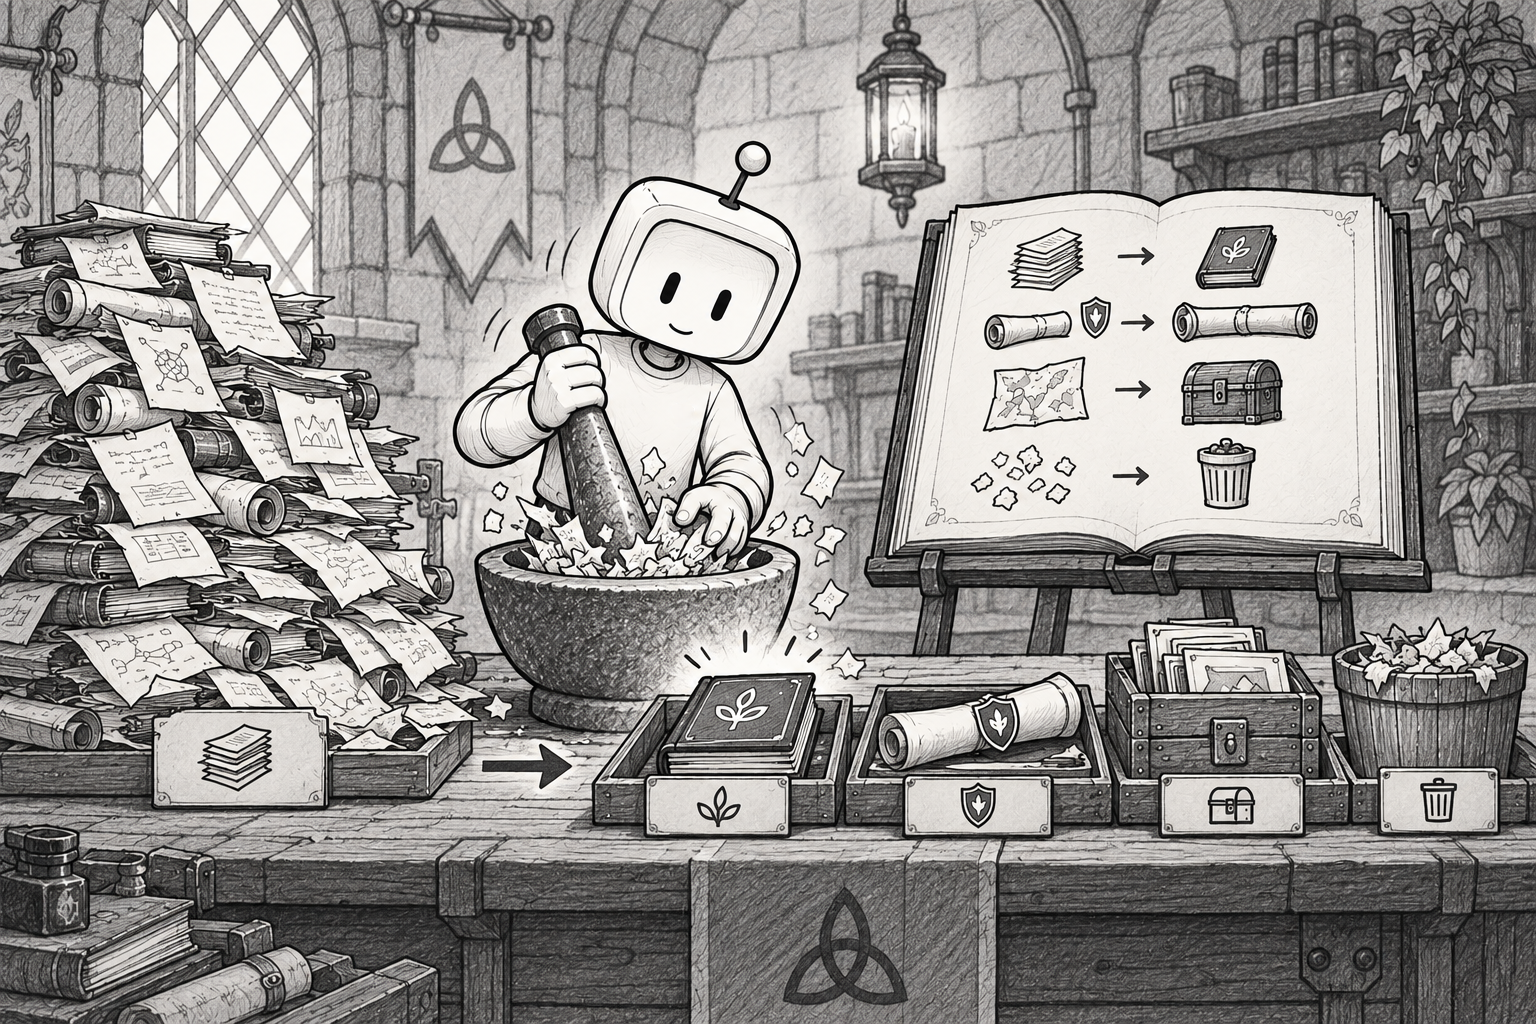
A coding assistant has spent forty turns investigating a failure. Its current state includes one security constraint, repeated logs, a useful hypothesis, two rejected approaches, tool outputs from older builds, and an API reference.
The next call cannot carry all of that material forever. Something has to decide what remains exact, what can be represented more briefly, what can be fetched again, and what can leave.
That decision is compaction: reducing active context while trying to preserve the state the task still needs. Compaction is not a hidden ability of the language model. It is policy implemented by an application, agent runtime, or provider feature around model calls.
Its central tradeoff is unavoidable:
large prior context
-> select and transform information
-> smaller current representation
-> some detail survives and some does not
-> later behavior depends on what survived
Every strategy has a preserve/lose profile
Several mechanisms are often grouped under the word compaction. They do not make the same choices.
| Strategy | Preserves best | Loses first | Useful when | Primary risk |
|---|---|---|---|---|
| Truncation | A hard size cap and whichever content remains | Whatever falls beyond the cutoff, possibly without regard to meaning | A system must enforce a limit after safer policies are exhausted | Critical older constraints disappear silently |
| Sliding window | Recent turns and immediate local intent | Older decisions, evidence, and commitments | Recency reliably dominates the task | An old but still active requirement leaves the window |
| Summarization | Major decisions, narrative progress, and selected state | Exact wording, uncommon details, edge evidence, and source structure | Long-horizon continuity matters more than a verbatim record | Omission or distortion becomes the new working state |
| Retrieval-backed reinjection | Exact stored material selected for the current need | Anything retrieval fails to find, rank, or refresh | Precise evidence is needed only for some turns | Missing, stale, or badly represented evidence is treated as recovered |
No row is the universal winner. A creative conversation may tolerate a compact narrative summary. A policy decision may require exact clauses and dates. A coding task may preserve the current failing test and retrieve API documentation only when the active hypothesis needs it.
The right comparison is not Which strategy compresses most? It is Which losses can this task safely absorb, and which losses must remain visible or recoverable?
Summaries are new representations
Suppose a conversation contains this decision:
Keep the legacy parser until the mobile client reaches version 6.2.
Do not remove it merely because the web migration passes.
A summary later says:
The team plans to remove the legacy parser after migration testing.The summary is shorter and broadly related. It has also lost the mobile-version condition and changed the decision’s trigger. If the original messages are discarded, later calls may act on the altered representation with no way to reconstruct what was said.
This is why summarization should not be described as lossless compression. A summary can omit a detail, merge two states, preserve stale information, or phrase uncertainty as a settled decision. Repeatedly summarizing summaries can compound those changes.
Useful summary policy states what the representation is for. A task-state summary might preserve:
- the active objective and acceptance criteria;
- constraints that remain in force;
- confirmed facts and their sources;
- unresolved questions and blockers;
- actions taken and their observed results;
- rejected paths and why they were rejected.
Even a careful schema does not guarantee fidelity. It makes the preservation target explicit enough to evaluate.
Protect what must remain exact
Some information should not be entrusted to a general narrative summary. Depending on the workflow, protected context can include:
- current system or safety constraints;
- the user’s active objective;
- exact policy language or contractual requirements;
- unresolved approvals and prohibitions;
- source identifiers needed to recover evidence;
- the latest authoritative tool result;
- output format requirements that downstream software validates.
“Protected” does not have to mean replayed verbatim forever. It means the compaction policy is not allowed to discard or weaken the information silently. The system might keep it exact in current context, store it externally and retrieve it when relevant, or stop and ask for review when it cannot preserve the required fidelity.
This is application responsibility. The model processes the representation it receives. It does not independently know that one sentence came from an authoritative policy while another came from a speculative earlier answer unless the surrounding system preserves that distinction.
Retrieval is not the compacted context
Retrieval-backed reinjection separates storage from per-call context:
original source stored outside the model
-> current task creates an information need
-> retrieval fetches candidates
-> application filters, ranks, trims, or summarizes them
-> selected representation enters current context
Retrieval decides what to fetch. Context construction decides what the model actually receives and in what form. A retrieved passage may still be dropped for budget, truncated before the decisive sentence, reordered, combined with stale material, or summarized incorrectly.
It is therefore useful for recoverability, not automatic correctness. Retrieval quality, permissions, source authority, freshness, and reinjection format all remain part of the path.
Fresh state may need replacement, not accumulation
Long sessions naturally collect older versions of the same fact: an earlier test failure, a previous account balance, an outdated policy, or a tool result from before a deployment.
Keeping every version can preserve history while making the active state ambiguous. A context policy needs to distinguish at least three cases:
- Current state: the latest authoritative observation needed for the task.
- Historical state: an older observation retained because change over time matters.
- Superseded state: an older observation that should leave active context or be clearly marked as obsolete.
This is not merely a token-saving move. Replacing stale state can improve the clarity of the evidence presented to the model. When the source can change, a previous result should not be considered correct merely because it is already in the transcript.
A compaction policy for the coding session
Return to the forty-turn debugging session. One reasonable policy might look like this:
| Information | Treatment | Why |
|---|---|---|
| Security constraint from turn 3 | Preserve exactly | Losing it creates unacceptable risk |
| Current bug hypothesis | Keep exact and near the current task | It determines the next discriminating action |
| Latest failing test output | Keep exact until superseded | It is current environmental evidence |
| Repeated copies of the same log | Deduplicate or drop | They add cost without adding information |
| Rejected approaches | Summarize with rejection reasons | Prevents repetition without replaying every exchange |
| API reference | Store and retrieve relevant sections on demand | Exact source matters only when the active step uses it |
| Output removed by compaction | Record in a compaction log | Makes loss inspectable during debugging |
This is an example, not a universal template. A low-risk brainstorming tool and a safety-critical policy assistant should make different preserve/lose decisions.
Observe the loss
Compaction becomes difficult to debug when the system exposes only the shortened context. Useful observability can record:
- which segments were dropped, retained, summarized, or marked stale;
- which source or prior state a summary represents;
- when compaction ran and what threshold triggered it;
- whether exact originals remain recoverable;
- which protected constraints were checked before the next call;
- whether retrieval failed or returned evidence of uncertain freshness.
Provider-managed compaction may expose a different contract. For example, OpenAI currently documents server-side and standalone compaction that carry an opaque compaction item into later Responses API calls. That is a specific provider mechanism. Applications using it should follow that API’s handling rules and evaluate whether task-critical state survives; the existence of a compacted item is not a vendor-neutral guarantee of lossless recall.
Choose by risk, not by habit
Compaction policy should answer four questions before it chooses a mechanism:
- What must remain exact for the next decision to be valid?
- What can be summarized without changing the task’s meaning?
- What can be recovered from an authoritative current source when needed?
- What can be dropped, and how will that loss be detected or explained?
The safest answer is rarely “keep everything until the API rejects it.” That postpones selection until the system is under maximum pressure. It is also rarely “summarize everything every twenty turns.” That treats unlike information as though it had the same fidelity requirements.
Compaction is controlled loss. A sound policy does not pretend otherwise; it aligns the loss with the task, protects decisive information, and keeps enough evidence to notice when the compacted representation is no longer adequate.
References
- CompactionOpenAI
- Conversation stateOpenAI
- Building effective agentsAnthropic
- Retrieval-Augmented Generation for Knowledge-Intensive NLP TasksNeurIPS, 2020