The Memory Illusion: Memory as a Construction
AI products create continuity by storing, selecting, and reinjecting information around otherwise stateless model calls; the model itself does not own the persistent record.
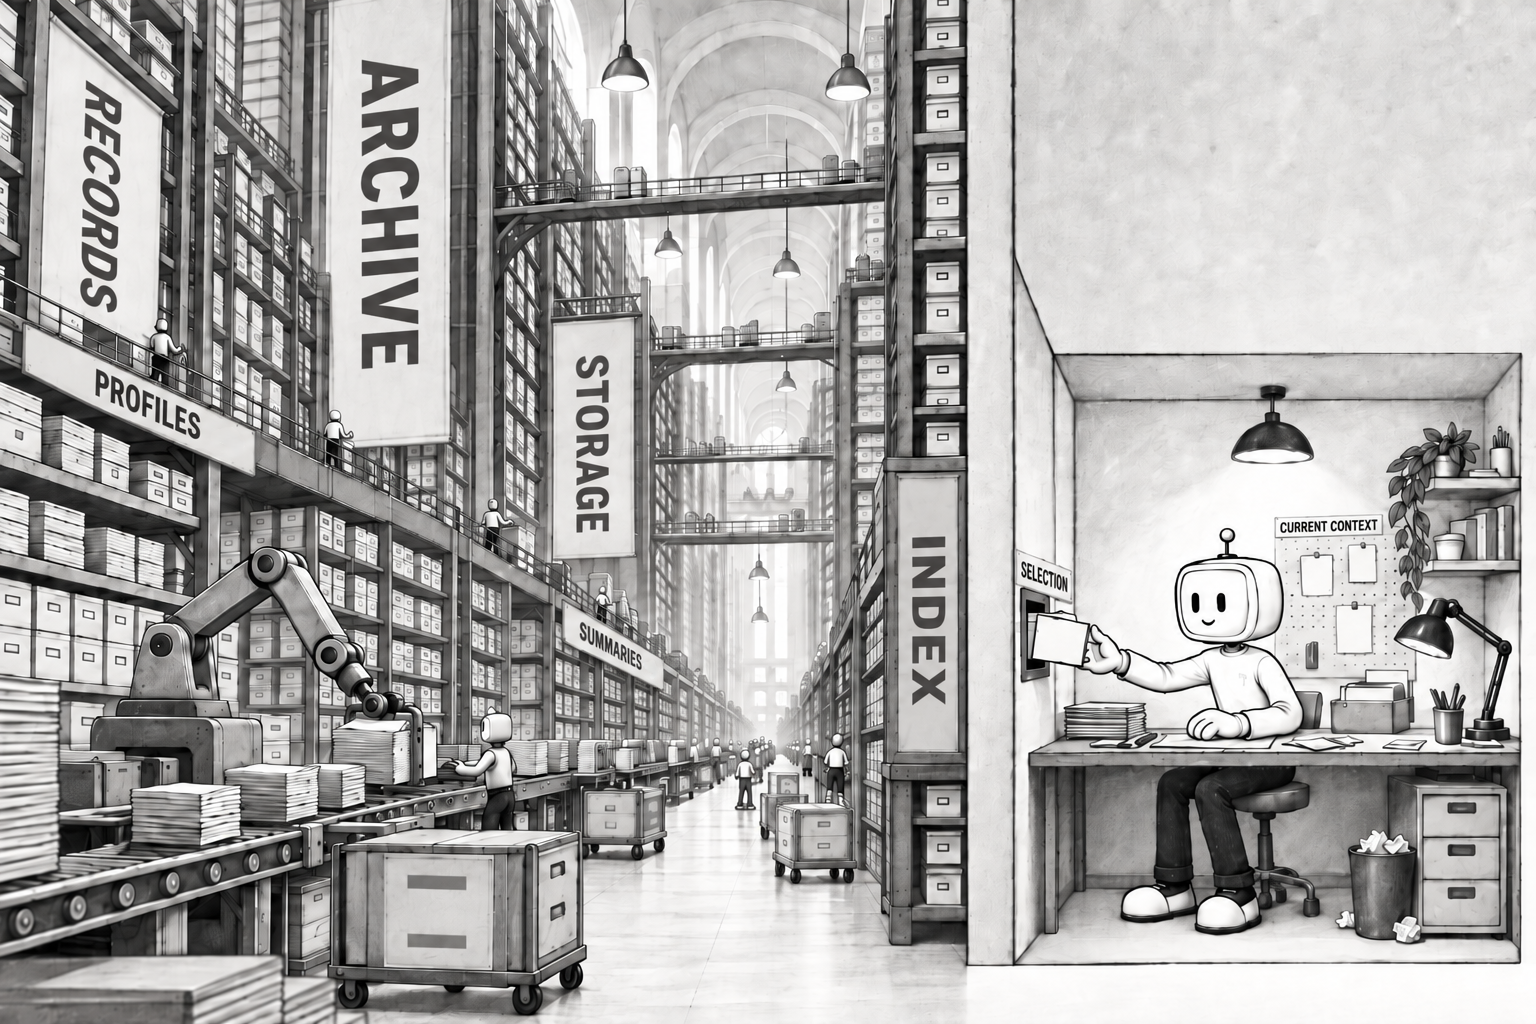
An AI product can greet you by name, continue yesterday’s project, and preserve a preference across sessions. The continuity is real. The misleading step is to assign all of it to the model.
A model call processes its parameters and the information made available for that invocation. Persistent continuity is usually constructed by software around the call: store something, decide whether it matters later, place a representation of it into a new request, then let the model respond to that request.
This lesson uses memory for that complete application-level capability. It does not use the word as a synonym for every place information can exist.
Across two model calls
Persistence lives outside the model- Interaction / 01A fact appears
The user says, "Call me Sam and send invoices by email."
- Application / 02Store
The host saves selected facts in a profile, summary, transcript, or database.
- Application / 03Select
A later request triggers a policy or retrieval step that chooses relevant state.
- Application / 04Inject
The selected fact becomes part of the current request context.
- Model / 05Generate
The model responds to the information supplied for this call.
Four places that are easy to collapse
The same product can involve several memory-like mechanisms at once. They have different owners and different failure modes.
| Place | What exists there | What it is not |
|---|---|---|
| Model parameters | Numerical patterns acquired during training and represented in a particular model version | A runtime database of this user’s conversations |
| Current context | Tokens or other input representations available to the present inference | Durable storage merely because the model can use it now |
| Application-managed storage | Transcripts, summaries, profile fields, files, database rows, vector indexes, or saved tool results | Automatically visible to every later model call |
| Prompt or computation cache | Reusable work under provider-specific matching and lifetime rules | A durable personal memory system |
The first row is often called parametric knowledge or, in research literature, parametric memory. It describes information encoded in model parameters. The second is the model’s present input. The third and fourth belong to systems around the model.
These distinctions protect an important point: information can persist without being in the model, and information can be in context without persisting after the call.
A later call needs a carrier
Suppose a user says:
For this account, call me Sam and send invoices by email.The current call can use that sentence because it is present now. For a call next week to use the same preference, some system must carry it across the boundary.
One product might replay the transcript. Another might save two structured profile fields. A third might create a summary. An API may maintain a conversation object or let the client refer to an earlier response. Those designs differ, but each has the same causal shape:
- Storage: software preserves the transcript, summary, preference, or reference.
- Selection: a policy or retrieval mechanism decides what is relevant to the later request.
- Context injection: selected material is placed into, or restored for, the new model call.
- Generation: the model conditions its output on the context it received.
If the application stores invoice preference: email but selects only name: Sam, the preference still exists in storage. It is simply unavailable to that model call. Storage is not access.
This is also why a larger context window is not the same as persistent memory. A larger window can hold more information for one call. It does not decide what survives between calls, where that information is kept, or which part should return later.
Conversation history is application state
Many chat interfaces make history feel intrinsic because the plumbing is invisible. The application can send earlier messages again, the provider can restore a managed conversation, or a framework can load a session before invoking the model.
In all three cases, continuity has an identifiable carrier. The model can use earlier turns because the system made them available again, not because every past interaction remains privately present inside a stateless invocation.
That boundary remains useful even when an API hides the replay. Ask two questions:
- Where is the prior state retained or referenced?
- How does it become input to this call?
Those questions turn “it remembers” into an architecture that can be inspected.
Parameters are knowledge, not personal history
A base model can answer a general question about SQL without retrieving a user’s profile. Patterns learned during training are already represented in its parameters. This is different from loading a fact such as Sam prefers email invoices at runtime.
The distinction is not that one path contains intelligence and the other contains raw data. Both can affect generation. They differ in provenance, update behavior, and control:
- parameter knowledge is compact and always participates in inference, but individual facts can be difficult to locate, cite, or update precisely;
- externally stored facts can be inspected and changed directly, but the application must select and supply them;
- current context can include either user state or retrieved knowledge without rewriting the model’s parameters.
The earlier lesson on training and the knowledge cutoff develops this durable-versus-runtime distinction in more detail. Supplying a newer fact can improve an answer without permanently teaching it to the base model.
Caches reuse work; they do not remember a person
Some providers can cache repeated prompt segments or other intermediate computation. That can reduce latency or cost when later requests reuse eligible material. Matching rules, lifetime, and invalidation behavior depend on the implementation.
A cache hit can make repeated context cheaper to process. It does not independently decide that a user preference is important, preserve it as a durable profile, or make it available after the cached material expires. Cache reuse is an optimization mechanism, not a synonym for persistent user memory.
Apparent forgetting has several owners
Once memory is split into stages, “the AI forgot” becomes a diagnosis rather than an explanation.
| Observation | Possible system cause |
|---|---|
| The preference was never available in a later session | Nothing persisted it, or the session reference was lost |
| The fact exists in a profile but was not used | Selection policy omitted it |
| A summary contains an older preference | Stored state is stale |
| The right fact was selected but not sent | Context assembly or API state restoration failed |
| The fact was supplied but the response contradicted it | The model ignored, misread, or was pulled away from the evidence |
| Earlier detail disappeared in a long thread | History was truncated, compacted, or displaced under a context limit |
These causes call for different remedies. Retrying the same prompt does not repair a missing database record. Expanding storage does not guarantee better selection. Supplying the correct fact does not guarantee that generation will use it faithfully.
“If the product saw it once, the model remembers it.”
A previous interaction can create information that the application chooses to retain. A later model call can use that information only when the system restores or supplies it according to its architecture. The model, application, provider, and external stores should not be treated as one memory-owning entity.
The practical model
When a feature claims to remember, map the path:
previous interaction
-> application stores selected information
-> a later interaction occurs
-> application retrieves or selects relevant state
-> selected state enters current context
-> model generates from that context
Real systems can use full transcripts, summaries, structured fields, search, response references, or combinations of them. The implementation choice is product-specific. The invariant is narrower: persistence outside the model only affects a call through some path back into what that call can use.
That path is the foundation for the rest of this chapter. Embeddings can help rank external information, and retrieval-augmented generation can supply selected evidence. Neither changes the basic boundary between stored state and current model context.
References
- Conversation stateOpenAI
- Prompt cachingAnthropic
- Retrieval-Augmented Generation for Knowledge-Intensive NLP TasksNeurIPS, 2020